Know when an agent goes wrong, and why, before a customer tells you.
A watcher with no AI in it that checks your agents against plain rules, a test set that runs after every change, and a log of why each decision was made. For agents we build, and for the ones you already have.
What our own monitor checks, in plain words.
A selection from the rules that watch our 34-agent system. Each one is a database query, not a judgement call. It opens the data read-only and cannot change anything.
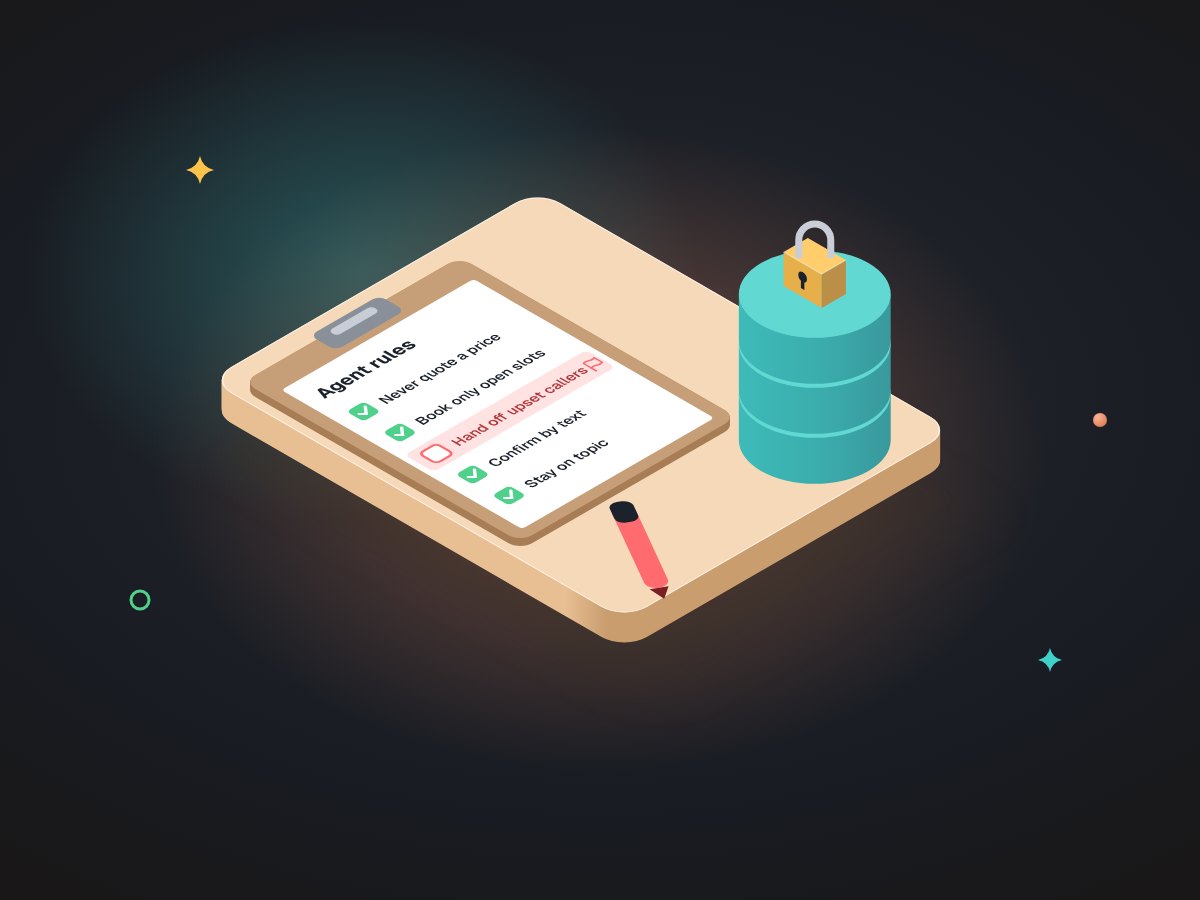
| Rule | Severity | What it recommends |
|---|---|---|
| The system is not answering | Critical | Restart it; the keeper log says why it stopped |
| Something shaped like a secret is in a log | Critical | Mask it, and change that secret |
| A note is filed in the wrong person's space | Critical | Keep it out of prompts at once; re-file once someone agrees |
| A job is stuck past its time limit | High | Mark it failed and tell whoever asked |
| A finished answer never reached the person | High | Deliver it now instead of waiting for a restart |
| An answer was posted twice | High | Hide the second copy |
| A model keeps failing | High | Route around that model until it recovers |
| An answer went out without its review | Medium | Find out why the reviewer did not answer in time |
| The same request was queued twice | Medium | Drop the later one if it has not started |
| A worker is corrected more often than not | Medium | Move that worker's outward work up a tier |
| A scheduled routine failed or did not run | Low | Read the routine's last runs |
One slow minute is not an alarm. One quiet minute is not a fix.
Three faults that never showed an error.
We test our agents against real cases, not demos. Each of these looked fine from the outside.
1 of 12 right, then 12 of 12
The small model that sorts requests had "thinking" mode on, which broke its structured answers. Turned off, it routed all 12 test requests correctly in about a second each.
A prompt cut off without a word
The local model's default window was 2,048 tokens. A 5,149-token prompt was silently truncated, so the agent answered half a question. Set to 16K, fixed.
"Draft an email" read as small talk
A 4B model treated a real request as chat and answered it itself. We put fixed rules in front of the model for the cases with one right answer.
A read-only check-up first.
If your phone or chat agent invents answers, talks over people or never hands off, this is where we start. We have not yet audited a client's agent; this is the method we use on our own.
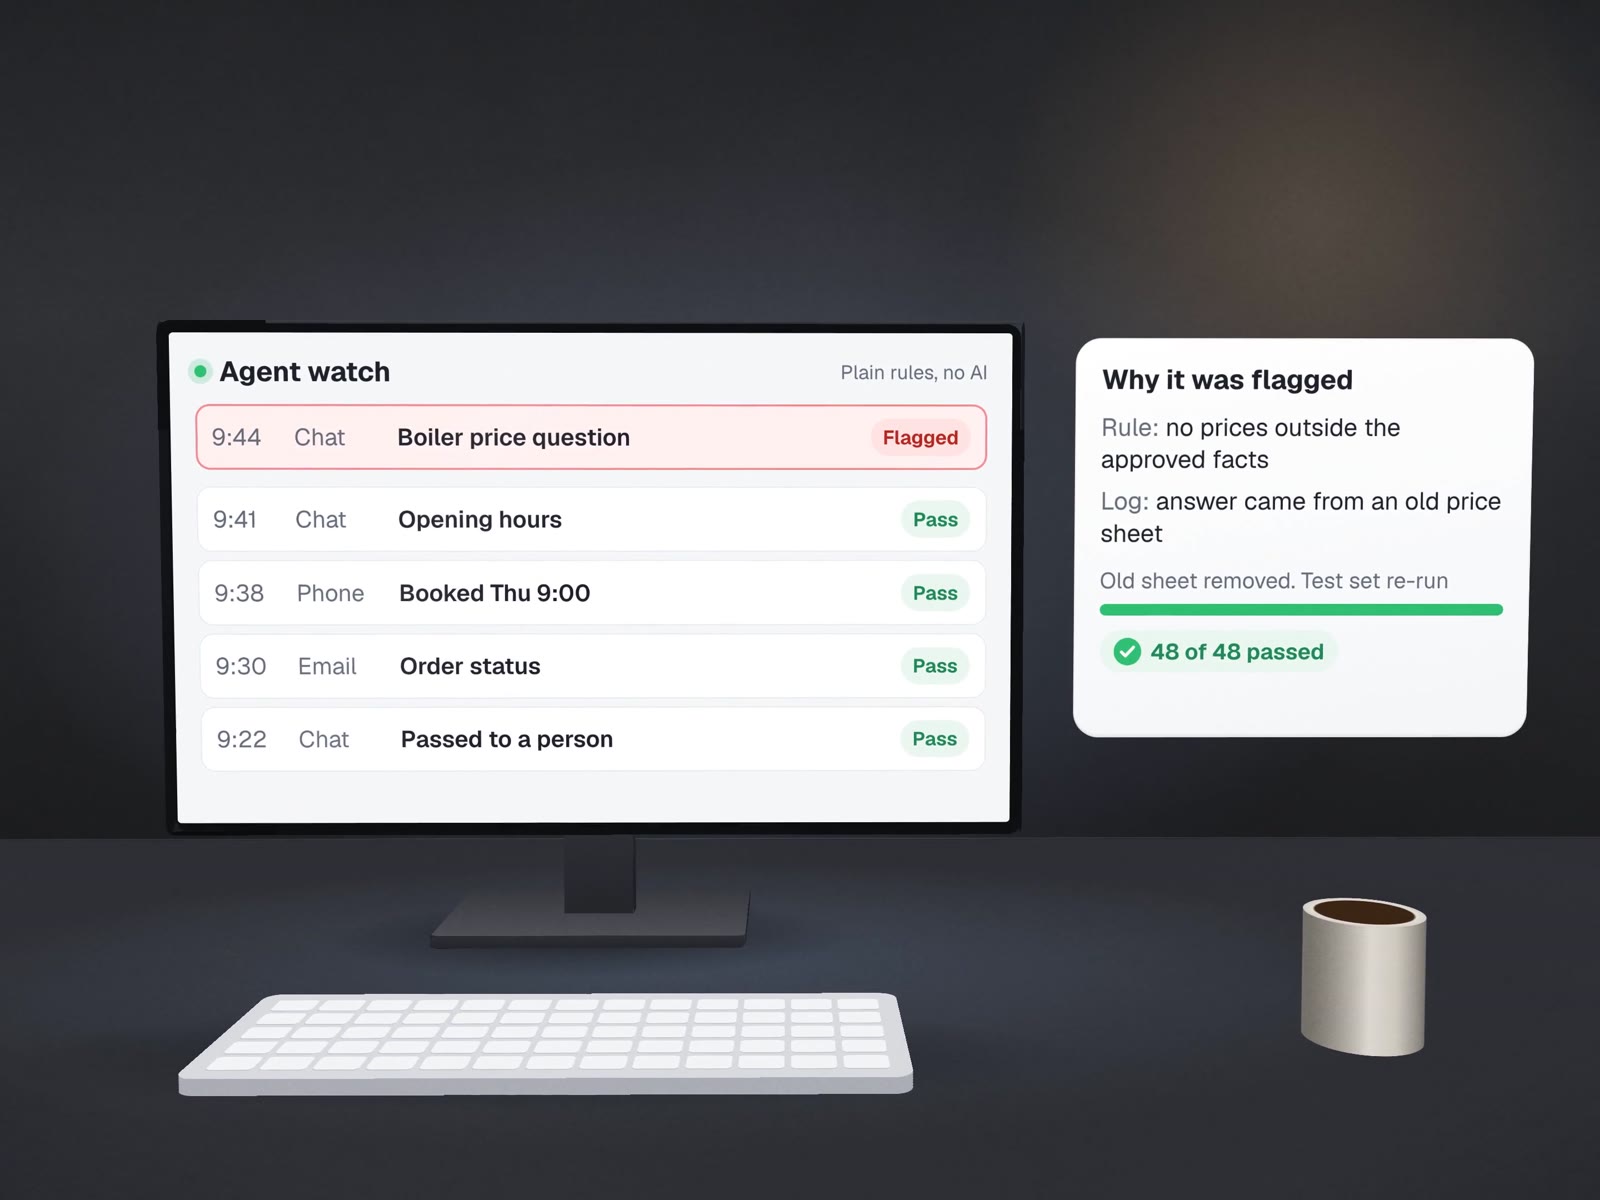
Read the job and the transcripts
Read-only access. We compare what the agent was told to do with what it did, and sort the failures: wrong answers, missed hand-offs, talking over people.
Turn each failure into a test
A question with the right answer or the right refusal. The set is re-run after every change from then on.
Add rules that watch it
Conditions like "a hand-off was promised and never logged", written as plain checks with a severity and a fix.
Log why it decided
Where the platform allows it, every route the agent takes is written down with its reason.
Report, then fix with your agreement
Written findings first. Nothing in your live agent changes until you have read them.
About watching agents.
Why monitor an AI agent with rules instead of another AI?
A model watching a model can drift, invent a problem or be argued out of a real one. A rule like "an answer finished but was never delivered" is either true in the data or it is not. We use models to build agents and rules to watch them.
Can you check an agent another company built for us?
Usually, as long as the transcripts can be exported and the instructions can be read. We start read-only and change nothing until you have the written findings and have agreed the fixes.
Will the monitoring see our customers' conversations?
The rules read what they must to check a condition, and the incident record keeps only ids and counts, not the private text. Our own monitor works this way.
More on keeping agents honest
The monitor's own case, the system it watches, and fixes for automations that are not AI.
Agent monitoring and testing
The full build of the monitor and the test suites.
Multi-agent systems
The 34-agent crew these rules watch.
Automation rescue
For Zapier, Make and n8n setups that fail quietly.
Phone answering agents
Built with these tests from day one.
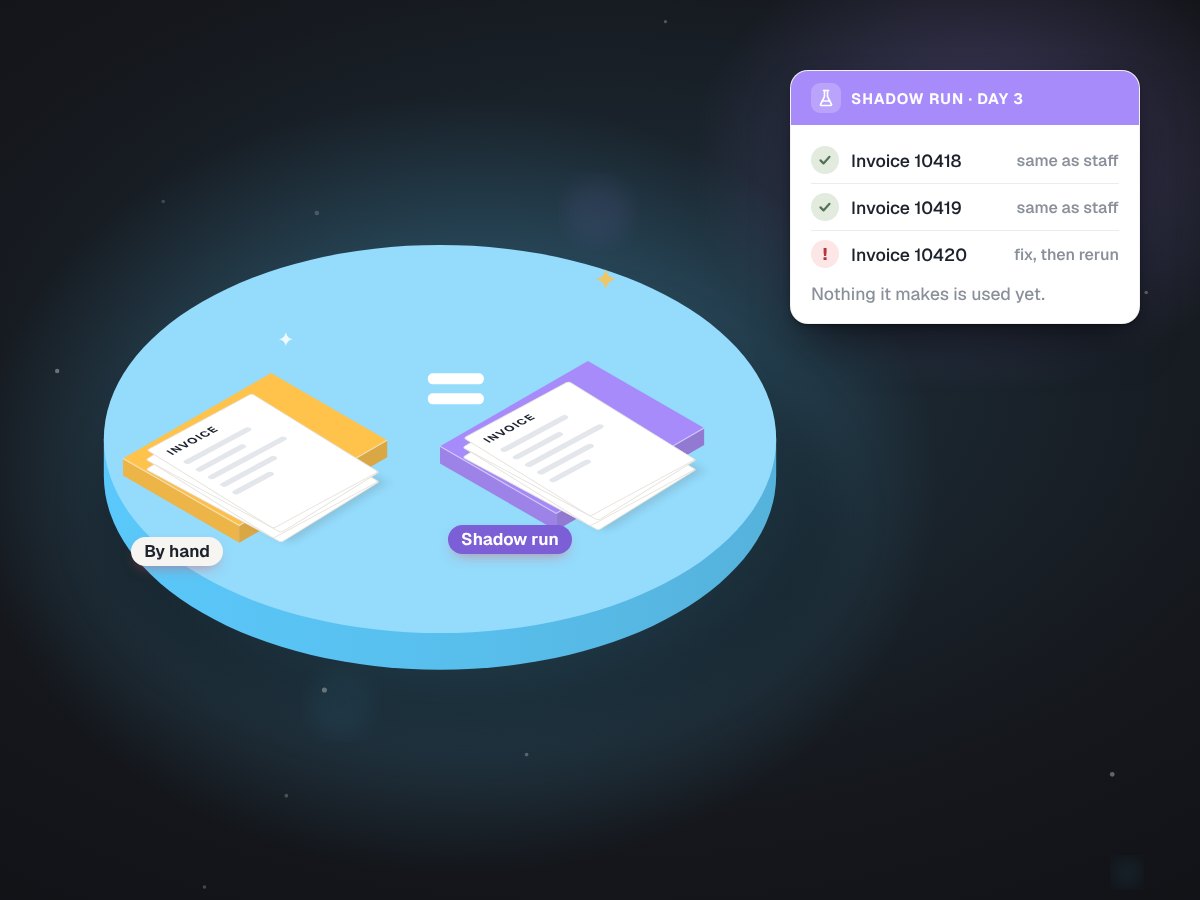
Test it on real paperwork first
The shadow run, before anything goes live.
Agent saying odd things? Send us one transcript.
On a free call we read it with you and tell you what a check-up would look at.